
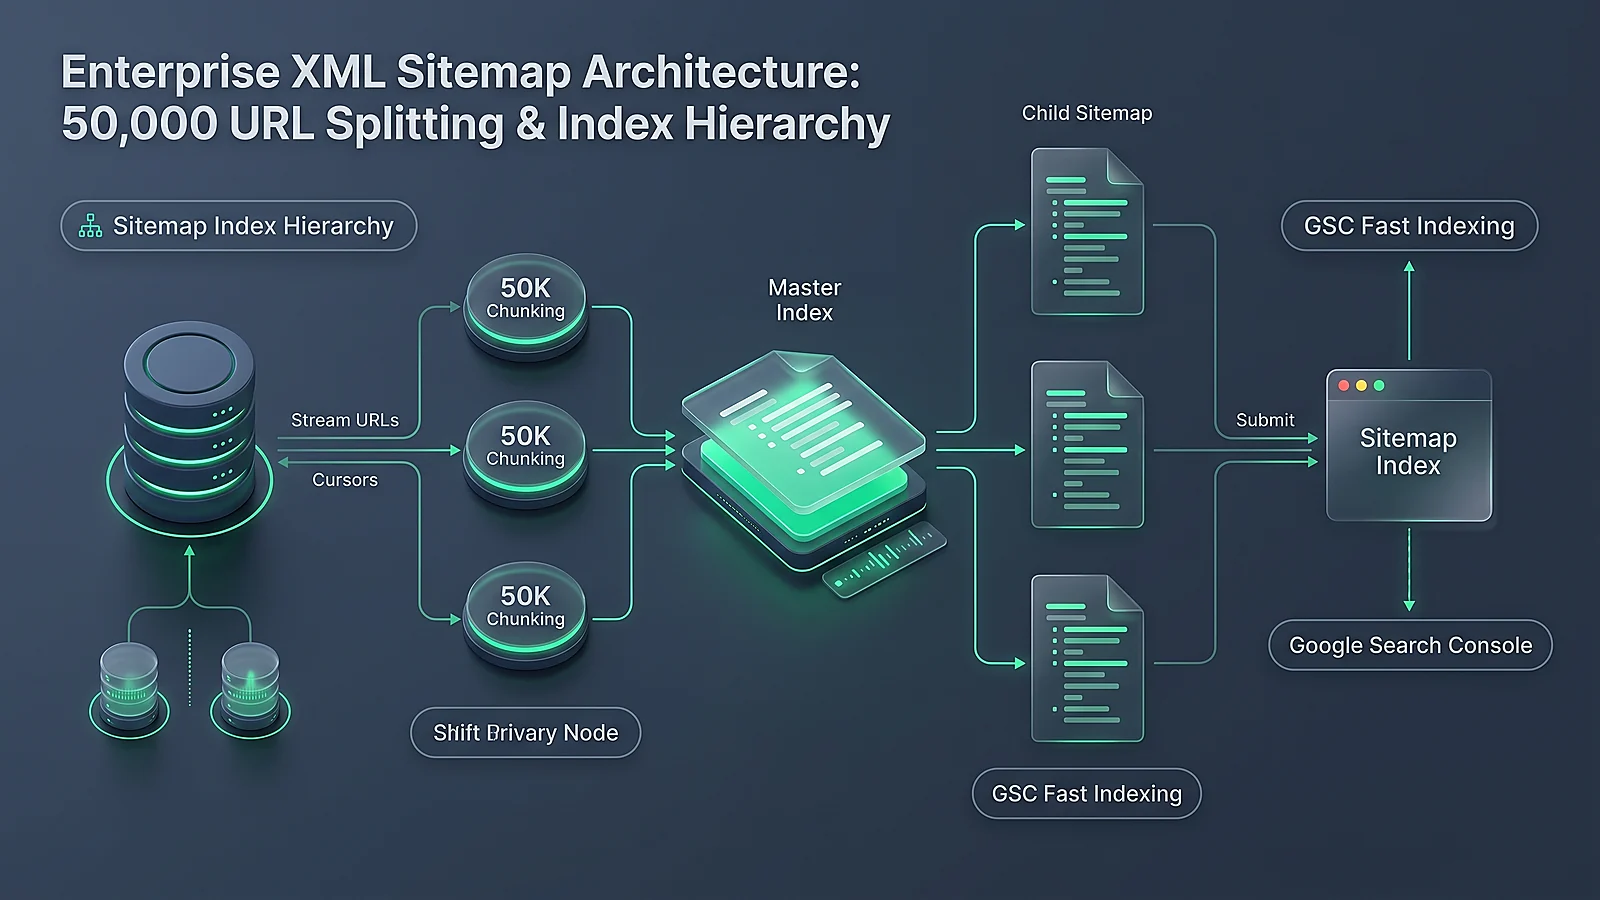
For enterprise websites, multinational e-commerce platforms, and high-velocity digital publications managing hundreds of thousands—or millions—of pages, the XML sitemap is a mission-critical data highway communicating page inventory directly to search engine crawlers. Establishing an automated, fault-tolerant XML sitemap architecture with sitemap index files and algorithmic 50,000-URL chunking ensures rapid discovery of newly published assets and granular diagnostic visibility inside Google Search Console.
The Mechanics of XML Sitemaps: Protocols, Limits, and Encodings
Formally standardized under the sitemaps.org schema and recognized by Google, Bing, and major global search engines, an XML sitemap provides crawlers with a structured roadmap of canonical URLs. However, webmasters often overlook the strict physical limitations enforced by search engine parsers.
1. Hard Specifications and Parsing Constraints
- The 50,000 URL Limit: A single XML sitemap file must never contain more than 50,000 individual URL records. Exceeding this boundary triggers parser rejection or partial truncation by Googlebot.
- The 50 Megabyte (MB) Limit: Uncompressed sitemap files must not exceed 50 Megabytes (52,428,800 bytes). When gzip compression (
.xml.gz) is applied, the uncompressed file payload must still comply with the 50MB ceiling. - Strict UTF-8 Encoding: All characters, query strings, and path tokens must be strictly UTF-8 encoded, with reserved XML entities properly escaped (e.g.,
&for&,<for<, and"for"). - Exact Canonicalization: Sitemaps should exclusively contain 200 OK, indexable, canonical URLs. Including redirected (301/302), broken (404/410), or noindexed pages wastes crawl bandwidth and degrades sitemap authority scores in Search Console.
Sitemap Index Hierarchy: Structuring Multi-Tier Architectures
When a web property expands beyond 50,000 URLs, the standard approach is to implement a Sitemap Index File (sitemap-index.xml). Rather than listing individual page URLs, a sitemap index acts as a master manifest pointing to dedicated child sitemaps.
1. Structural Anatomy of a Sitemap Index
A sitemap index file utilizes the <sitemapindex> root tag, enclosing multiple <sitemap> entries with their respective locations and modification timestamps:
<?xml version="1.0" encoding="UTF-8"?>
<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
    <sitemap>
        <loc>https://seobeen.com/sitemaps/products-1.xml.gz</loc>
        <lastmod>2026-09-29T18:00:00+00:00</lastmod>
    </sitemap>
    <sitemap>
        <loc>https://seobeen.com/sitemaps/products-2.xml.gz</loc>
        <lastmod>2026-09-29T18:00:00+00:00</lastmod>
    </sitemap>
    <sitemap>
        <loc>https://seobeen.com/sitemaps/articles-1.xml.gz</loc>
        <lastmod>2026-09-29T12:00:00+00:00</lastmod>
    </sitemap>
</sitemapindex>
2. The Multi-Segment Splitting Strategy (The 10K Rule)
While the official limit is 50,000 URLs per sitemap, enterprise SEO best practices strongly advocate for splitting sitemaps at 10,000 to 25,000 URLs rather than pushing against the maximum ceiling. This provides three decisive operational benefits:
- GSC Indexation Diagnostics: Search Console provides coverage breakdowns per individual child sitemap. If a sitemap containing 10,000 URLs only exhibits 3,000 indexed pages, technical teams can pinpoint the specific content category or database segment experiencing indexation drag.
- Reduced Parser Memory Overhead: Smaller files parse dramatically faster, minimizing origin server timeout risks during large-scale crawl passes.
- Efficient Incremental Updates: Regenerating a 10,000-URL file requires significantly less CPU and database locking overhead than rebuilding monolithic 50,000-URL files.
Enterprise Segmentation Matrix: Organizing Child Sitemaps
Segmenting child sitemaps by content type, revenue tier, or page velocity transforms the sitemap system into an enterprise diagnostic engine. The table below outlines high-performance segmentation models for large catalogs:
| Sitemap Child Segment | Target URL Capacity | Regeneration Frequency | Primary Business Purpose | Diagnostic Metric in GSC |
|---|---|---|---|---|
| Core Editorial Articles | 5,000 – 10,000 | Real-time on publish | Informational Organic Pipeline | Indexation Velocity (<24 hrs) |
| Category & Hub Silos | 1,000 – 5,000 | Daily batch sync | Topical Authority Pillars | Coverage Ratio (>98%) |
| Product Detail Pages (PDP) | 10,000 – 25,000 | Dynamic 6-hour cron | E-commerce Bottom-of-Funnel | Crawl vs Discovered Gap |
| High-Velocity News / Press | 1,000 (Last 48 hrs) | Sub-5-minute stream | Google News / Real-time Feed | Immediate SERP Inclusion |
| International Hreflang Clusters | 10,000 – 20,000 | Weekly audit cycle | Multi-Regional Routing | Hreflang Return Tag Errors |
Automated 50K Splitting Architecture in High-Scale Systems
In high-scale systems (such as Node.js, Python, or Go microservices), generating static XML sitemaps on-the-fly causes database connection exhaustion. The modern architectural pattern utilizes asynchronous streaming batch workers combined with Cloudflare Worker or AWS S3 caching.
1. Algorithmic Streaming and File Chunking Architecture
The diagram below conceptualizes the pipeline from origin database records through streaming chunkers to Google Search Console ping APIs:
[PostgreSQL / MySQL Master]
           |
     (Read Cursor / Batch 5,000 Rows)
           v
[Background Chunker Worker]
     ├── Buffer <url> nodes in memory
     ├── If Count >= 25,000 OR Size >= 35MB:
     │     ├── Flush to child_sitemap_N.xml.gz
     │     └── Register in sitemap_index.xml
           v
[Object Storage / Edge CDN (S3 + Cloudflare)]
           v
[Googlebot Fetch / GSC Diagnostic Dashboard]
2. The Lastmod Tag: Absolute Accuracy Protocol
The <lastmod> element is one of the few sitemap tags that Googlebot actively respects to prioritize re-crawling. However, search engines evaluate lastmod credibility strictly:
- W3C Datetime Format: Always use complete ISO 8601 formatting including timezone offsets (e.g.,
2026-09-29T18:00:00+00:00). - Zero Artificial Spoofing: Never mass-update
lastmodtimestamps for cosmetic changes, header shifts, or global site redesigns. If Googlebot re-crawls pages and detects no substantial text updates, it will permanently disregard lastmod signals across your entire domain.
Auditing and Eliminating Sitemap Cleanliness Errors
A sitemap is an explicit vote of confidence in page quality. Submitting low-quality, redirected, or dead links damages search engine trust and wastes crawl budget.
1. Identifying Status Code Pollution
Ensure your sitemap pipeline automatically filters out non-200 responses. Submitting URLs returning 301 redirects, 404 errors, or 500 server crashes dilutes indexation efficiency. Review our comprehensive guide on HTTP status codes and redirection guide to build automated status validators.
2. Canonical and Robots.txt Alignment
Every URL present in an XML sitemap must adhere to two absolute conditions:
- Self-Referential Canonical: The URL must declare itself as the canonical version via
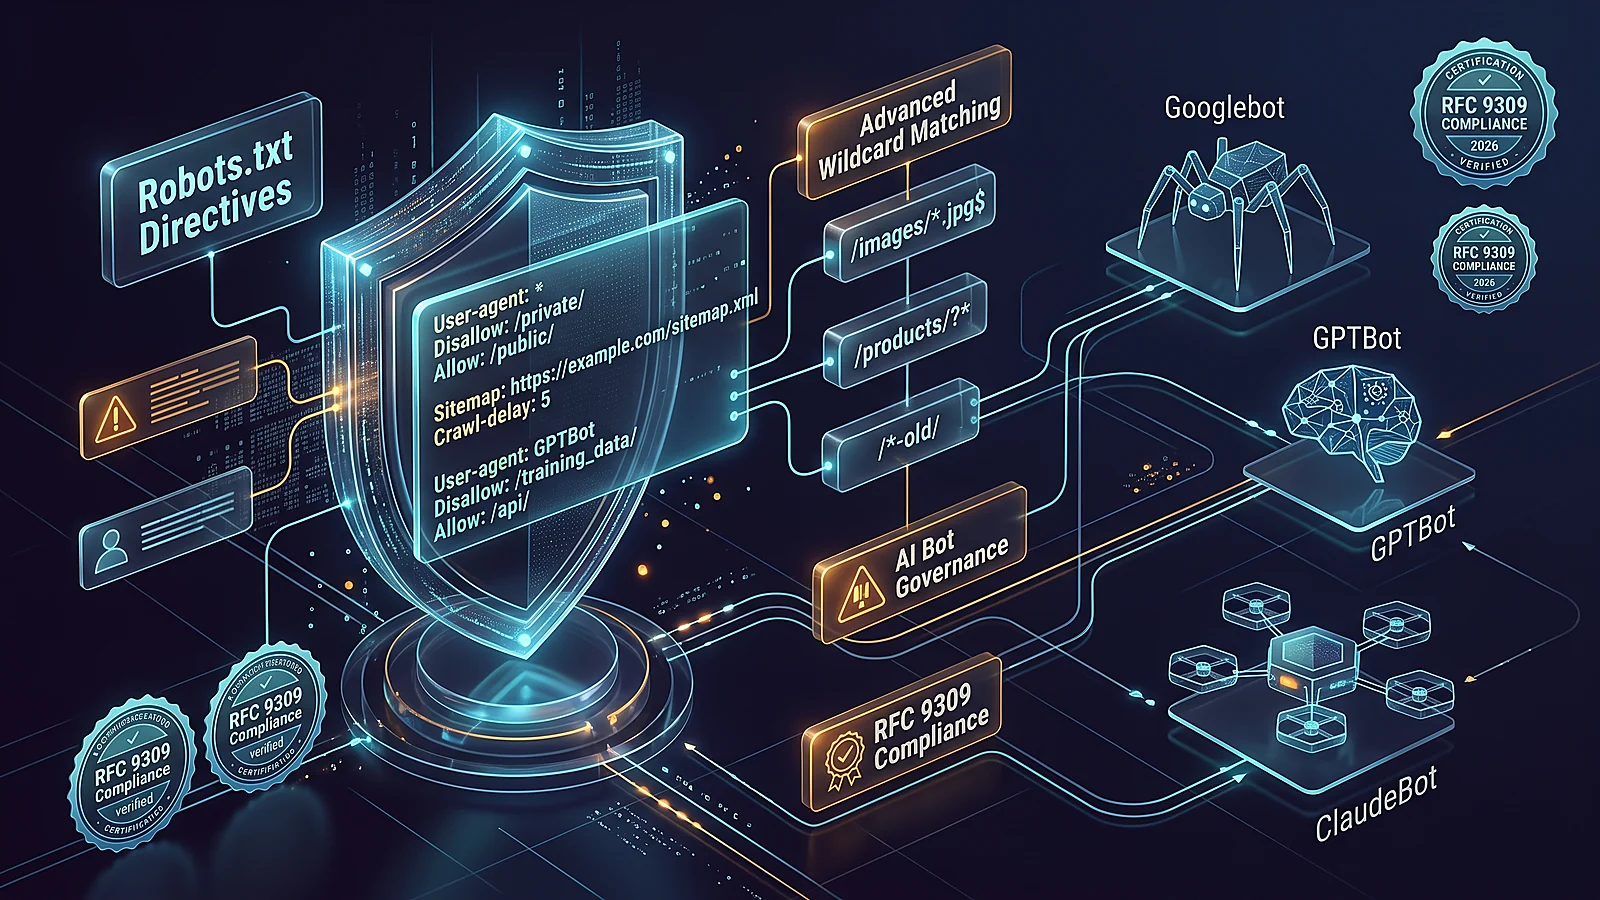
<link rel="canonical" href="...">. Never include non-canonical URLs in sitemaps. - Accessible in Robots.txt: The URL must not be blocked by robots.txt directives. Disallowing a sitemap URL creates an irreconcilable paradox for search engine crawlers. Learn how to craft bulletproof crawl boundaries in our guide to advanced robots txt directives.
Frequently Asked Questions
What is the maximum number of URLs allowed in an XML sitemap?
Under the official sitemaps.org protocol, a single XML sitemap can contain up to 50,000 URLs and must not exceed 50MB in uncompressed file size. If your website exceeds either threshold, you must split your URLs across multiple child sitemaps and unify them using a master sitemap index file.
Does Google respect the priority and changefreq tags in XML sitemaps?
No. Google officially ignores both the priority tag and the changefreq tag in XML sitemaps, as webmasters historically abused these values with inaccurate claims. However, Google heavily relies on the lastmod tag when it accurately reflects genuine content modifications.
Should I gzip compress my XML sitemaps before publishing?
Yes. Gzip compression (saving files with a .xml.gz extension) reduces sitemap file sizes by up to 80% to 90%, drastically reducing server bandwidth consumption and accelerating crawler download speeds. All major search engines, including Google and Bing, natively decompress and read .xml.gz sitemap files.
Where should the sitemap index file be declared?
You should declare your sitemap index URL at the bottom of your robots.txt file using the Sitemap directive (e.g., Sitemap: https://example.com/sitemap_index.xml), and submit it directly through the Sitemaps report in Google Search Console and Bing Webmaster Tools for immediate tracking.

Ratings & reviews
No reviews yet. Be the first.