
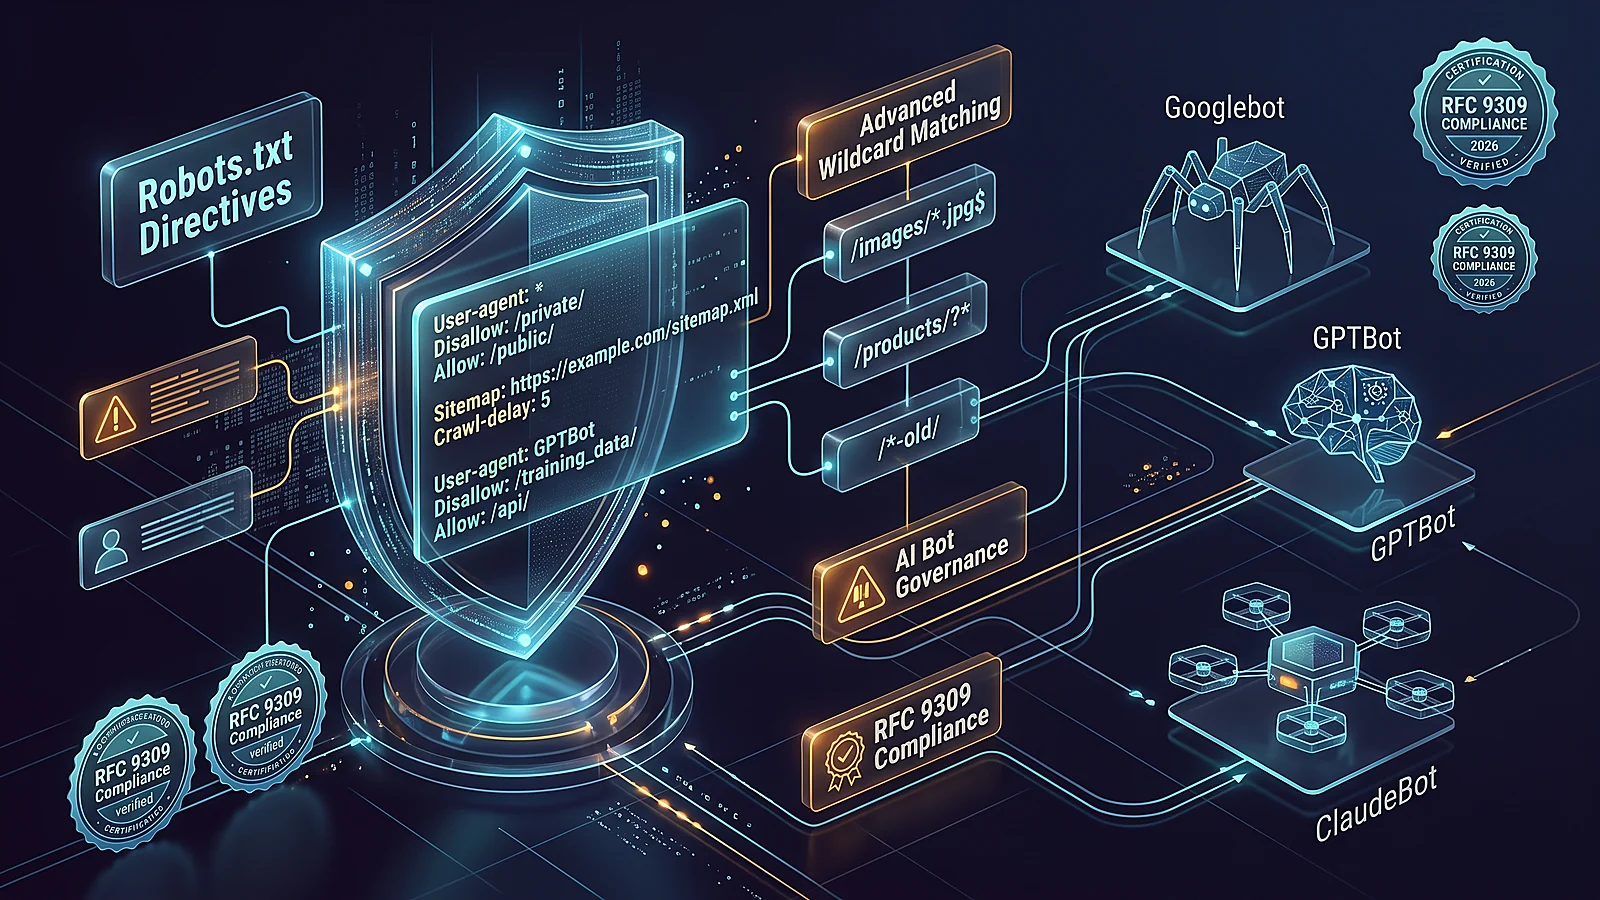
In the modern technical SEO ecosystem, the robots.txt file is far more than a rudimentary access gatekeeper; it is an authoritative protocol governing how search engine crawlers, autonomous AI indexing bots, and web scrapers allocate computational budget across your digital properties. Codified under the official IETF RFC 9309 specification, understanding the precise parser mechanics, wildcard pattern matching, and record precedence is vital for protecting crawl budget and preventing disastrous indexing blunders.
The Evolution of the Robots Exclusion Protocol: RFC 9309 Formalization
For more than two decades, the Robots Exclusion Protocol (REP) operated as an informal de facto standard established by Martijn Koster in 1994. Different search engine crawlers interpreted ambiguous directives, whitespace variations, and character encodings with disparate parsing logic. This ambiguity frequently caused catastrophic SEO regression—such as Googlebot indexing staging environments while Bingbot ignored crawl boundaries.
In September 2022, the Internet Engineering Task Force (IETF) formally standardized REP as RFC 9309. This formal specification established ironclad parsing rules that all compliant crawlers—including Googlebot, Bingbot, Applebot, and modern AI training bots—must obey:
- File Size Ceiling: Compliant parsers are only required to read up to 500 Kibibytes (KiB) of a robots.txt file. Any directives placed beyond the first 512,000 octets are silently truncated and completely ignored by search engine user-agents.
- Line-by-Line Execution: Parsers evaluate records sequentially by line, stripping inline whitespace, comments designated by the hash symbol (
#), and invalid syntax without discarding valid records. - Character Encoding: The specification strictly requires UTF-8 encoding. Files containing Byte Order Marks (BOM) or non-UTF-8 characters risk parser failure or unexpected character matching errors.
- Status Code Fail-Safes: A
5xx Server ErrorHTTP status halts all crawling on the domain, as search engines assume site instability. In contrast, a404 Not FoundHTTP status indicates zero restrictions, granting crawlers unrestricted access to all URLs.
Syntax Parsing Mechanics: Directives, Grouping, and Precedence
A compliant robots.txt file consists of one or more directive blocks separated by blank lines. Each block begins with one or more User-agent declarations, followed by specific path access rules. Understanding how parsers evaluate conflicting rules is crucial for complex multi-tier web applications.
1. User-Agent Grouping and Specificity
When Googlebot crawls a website, it evaluates user-agent blocks using the principle of maximum specificity. Googlebot will match the most specific declaration available rather than concatenating general and specific rules:
# Example: Specificity Precedence
User-agent: Googlebot
Disallow: /checkout/
Allow: /checkout/thank-you

User-agent: *
Disallow: /private/
Disallow: /checkout/
In this architecture, Googlebot exclusively adheres to the Googlebot block and completely disregards the wildcard * block. Therefore, /private/ is accessible to Googlebot unless explicitly disallowed within the dedicated User-agent: Googlebot group.
2. Path Precedence: The Longest Match Rule
RFC 9309 mandates that when multiple directives match a given URI, the directive with the longest path pattern takes precedence. If an Allow directive and a Disallow directive possess identical path lengths, the Allow directive wins by default:
# Path length tie-breaking
Allow: /products/apparel     # 17 characters (WINNER)
Disallow: /products/        # 10 characters (LOSER)

# Exact length tie
Disallow: /account          # 8 characters
Allow: /account             # 8 characters (WINNER: Allow overrides Disallow on tie)
Advanced Pattern Matching: Wildcard (*) and End-of-Line ($) Operators
Modern search engine parsers support two specialized pattern-matching characters that provide quasi-regular expression capabilities without the computational overhead of full regex engines.
1. The Wildcard Operator (*)
The asterisk denotes zero or more occurrences of any valid ASCII character. In robots.txt path matching, all rules inherently begin with an implicit wildcard unless specified otherwise. Consider how the wildcard operator operates across common enterprise scenarios:
# Block all URLs containing the parameter 'sort='
Disallow: /*sort=*

# Block all search internal query pages
Disallow: /*?s=*
Disallow: /*?search=*

# Block all PDFs across any subfolder
Disallow: /*.pdf$
2. The End-of-Line Anchor ($)
By default, robots.txt directives perform prefix matching. A directive such as Disallow: /catalog will block /catalog, /catalog-summer, and /catalog/shoes/. To restrict matching to an exact terminus, append the dollar sign ($) anchor:
# Blocks ONLY the exact root /catalog (not /catalog/ or /catalog-items)
Disallow: /catalog$

# Block specific image formats without restricting dynamically generated versions
Disallow: /*.gif$
Disallow: /*.bmp$
Comparative Analysis of Robots Directives Across Major Parsers
Not all search crawlers evaluate non-standard directives uniformly. The following table provides an authoritative overview of directive support, parser constraints, and behavioral outcomes across modern web search and AI crawlers:
| Directive / Feature | Googlebot | Bingbot | Applebot | GPTBot / ClaudeBot | RFC 9309 Standard |
|---|---|---|---|---|---|
| User-agent | Supported | Supported | Supported | Supported | Mandatory Core |
| Allow | Supported | Supported | Supported | Supported | Mandatory Core |
| Disallow | Supported | Supported | Supported | Supported | Mandatory Core |
| Sitemap | Supported (Anywhere) | Supported (Anywhere) | Supported (Anywhere) | Ignored | Mandatory Core |
| Crawl-delay | Unsupported (Deprecated) | Supported (Seconds) | Unsupported | Unsupported | Non-Standard |
| Noindex (via txt) | Unsupported (404/Ignore) | Unsupported | Unsupported | Unsupported | Prohibited |
| Max File Size | 500 KiB | 500 KiB | 500 KiB | 500 KiB | 500 KiB Default |
AI Crawler Governance in 2026: Protecting Proprietary Intelligence
The explosive rise of Large Language Models (LLMs) and autonomous retrieval agents has introduced a new class of user-agents designed specifically for AI training datasets and real-time retrieval-augmented generation (RAG). Proper robots.txt architecture requires deliberate separation between commercial search indexers and generative scraping bots.
1. Identifying Generative Engine and LLM User-Agents
Modern enterprise publishing platforms must manage dedicated records for major frontier model crawlers:
GPTBot: OpenAI's foundational model training scraper.ChatGPT-User: Real-time search requests initiated directly by ChatGPT subscribers.ClaudeBot: Anthropic's training crawler for Claude foundation models.Google-Extended: Google's explicit control switch for Gemini and Vertex AI training datasets.PerplexityBot: Perplexity AI's real-time indexer and citation retrieval agent.Bytespider: ByteDance's aggressive content scraper.
2. Enterprise AI Access Control Template
Below is a production-hardened robots.txt configuration balancing organic search visibility with proprietary data protection:
# Global Default Rules for General Search Crawlers
User-agent: *
Disallow: /admin/
Disallow: /api/
Disallow: /cart/
Disallow: /checkout/
Disallow: /wp-json/
Disallow: /*?*filter=
Disallow: /*?*sort=
Allow: /wp-admin/admin-ajax.php
Allow: /api/public/

# Allow Real-Time Search AI Agents for Citation Traffic
User-agent: ChatGPT-User
Allow: /

User-agent: PerplexityBot
Allow: /

# Restrict Mass LLM Offline Training Crawlers
User-agent: GPTBot
Disallow: /private-research/
Disallow: /premium-content/

User-agent: ClaudeBot
Disallow: /private-research/
Disallow: /premium-content/

User-agent: Google-Extended
Disallow: /

# Sitemap Declarations
Sitemap: https://seobeen.com/sitemap.xml
Implementing targeted disallow blocks preserves high-intent conversational citation traffic while preventing wholesale replication of your intellectual property. For deeper insights into managing crawl frequency and server overhead, explore our comprehensive framework for enterprise crawl budget management.
Five Critical Robots.txt Architectural Pitfalls
Even minor oversights in robots.txt syntax can cascade into severe organic traffic drops across enterprise digital architectures. Always avoid the following high-risk mistakes:
1. Blocking Critical JavaScript, CSS, or API Assets
Since the rollout of Google's Web Rendering Service (WRS), Googlebot executes JavaScript and renders complete Document Object Models (DOM). Blocking CSS stylesheets, JavaScript bundles, or image assets via robots.txt prevents the crawler from determining page layout, mobile responsiveness, and dynamic content visibility, resulting in algorithmic ranking penalties.
2. Attempting to De-index Pages via Robots.txt
One of the most persistent misconceptions in technical SEO is adding Disallow rules to eliminate low-quality or duplicate URLs from Google's index. If a page is disallowed in robots.txt, Googlebot cannot fetch the HTML payload to read the <meta name="robots" content="noindex"> tag. The proper protocol requires keeping the URL crawlable while serving a native noindex meta response or 410 Gone status.
3. Relying on Deprecated Crawl-Delay Directives for Google
Google officially stopped supporting the Crawl-delay directive in 2019. Attempting to throttle Googlebot using Crawl-delay: 10 is completely ineffective. To manage crawler velocity, configure server rate-limiting via Cloudflare, optimize origin server response times (TTFB), or leverage Google Search Console's crawl rate settings.
4. Omitting the Trailing Slash on Directory Restrictions
Writing Disallow: /archive blocks /archive/, but it also inadvertently disallows /archive-news, /archives-2026, and /archived-case-studies.html. When disallowing a specific directory, always ensure the trailing slash is included: Disallow: /archive/.
5. Failing to Validate with Real Server Log Files
Third-party robots.txt testers simulate crawler behavior based on idealized specifications, but actual crawler request cycles frequently exhibit subtle edge-case behaviors. Regularly cross-reference crawl access via server log file analysis to confirm that critical user-agents are executing directives without bottlenecking legitimate crawl demand.
Crawl Stats report within 24–48 hours to confirm zero drop in valid HTML crawl requests. Explore our broader library of Enterprise SEO Guides to refine your crawl infrastructure.Frequently Asked Questions
What is the difference between robots.txt disallow and the noindex meta tag?
Robots.txt disallow prevents search engine crawlers from fetching and downloading the page's HTML content. The noindex meta tag (or X-Robots-Tag HTTP header) instructs search engines to remove or omit the page from search results. If you disallow a page in robots.txt, crawlers cannot see the noindex tag and may still index the URL if external links point to it.
Can robots.txt be used to hide sensitive customer or admin data?
No. Robots.txt is a publicly accessible file located at the root of your domain (e.g., example.com/robots.txt). Malicious scrapers, bad actors, and vulnerability scanners routinely inspect robots.txt to discover hidden admin directories, staging URLs, and private paths. Secure sensitive assets with server-level authentication, VPNs, or IP whitelisting.
How frequently does Googlebot re-fetch the robots.txt file?
Googlebot typically caches robots.txt contents for up to 24 hours. If the file cannot be reached due to a 5xx server error, Googlebot may extend the cached version for up to 30 days before completely halting site crawling. You can request an immediate cache purge via Google Search Console's robots.txt submission tool.
Does robots.txt support full regular expressions like PCRE or ECMAScript?
No. Under the RFC 9309 specification, robots.txt only supports two pattern-matching operators: the asterisk (*) for wildcard matching of zero or more characters, and the dollar sign ($) for matching the exact end of a URL path. Complex regex features like character classes ([0-9]), lookaheads, or quantifiers are not supported.

Ratings & reviews
No reviews yet. Be the first.